UwView is a CLI and GUI program for investigating huge text and log files. What is new about it is that the two are interchangeable. Search from the terminal, add -open, and the hits appear in the window where you can read around them; narrow it there, then drop back to a command. Both sides run the same engine over the same index, so switching costs nothing — the file is never re-scanned just because you changed tools.
Open it and scroll all the way to the end. The whole file is viewable, scrollable and searchable from the moment you open it — you can scroll a 258 GB file down to its last line, or anywhere in the middle, without waiting for an index. Indexing runs in the background; line numbers appear when it finishes. The file is never loaded into memory: UwView memory-maps it and draws only the visible lines, so memory stays flat whatever the size. Verified on a 48 GB / 892-million-line file and a 258 GB / 4.5-billion-line one (OpenStreetMap Japan and United States).
Search as fast as grep. The free edition ships a uvf command that reads the file in a single pass. Measured on a Mac (M4, external USB SSD) against ripgrep 15.2.0 on the same file, cold cache: 3 GB / 100 million lines, 3.32 s against ripgrep's 3.26 s; 10 GB, 10.48 s against 10.96 s; 50 GB, 50.82 s against 54.76 s. It prints line<TAB>text to stdout and returns grep's exit codes (0 found / 1 not found / 2 error), so it drops into a pipeline or a cron job. It is not a drop-in grep replacement, though: no recursive search, no globbing, no -o.
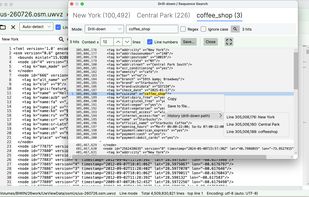
In the window: encoding auto-detection (UTF-8, Shift_JIS, EUC-JP, UTF-16), multi-keyword regex highlighting, saved filters, a non-modal results list with jump-to-line and ±N lines of context, and real-time tail. Windows, macOS and Linux.
A browser build, nothing to install. Drag a file into the page and it opens — no upload, the file stays on your machine. It is slower than the desktop build, but for 3 GB and around 100 million lines it is comfortable enough to do real work in.
For investigating the same log again and again, there is UwView Pro. It keeps a persistent index and a compressed cache: from the second open the file appears instantly with line numbers, and a log can be archived at about 1/9 of its size and still be searched without unpacking. Its uvp command adds drill-down (up to 8 stacked stages), tallies, ordered search and replace. Against ripgrep on the same files: 4.6-7x at 10 GB, 7.1-8.7x at 50 GB, about 7.8x at 258 GB. At 3 GB it is 2.6x with a cold cache, and ripgrep wins once the file is sitting in RAM.
Free for personal and internal company use under the PolyForm Internal Use License 1.0.0; source is on GitHub. Redistribution or embedding requires a commercial licence.
Honest note: the first open still has to read the file once, at the speed of your storage. What UwView changes is that you can read and search it while that happens.




 amru195704


